4
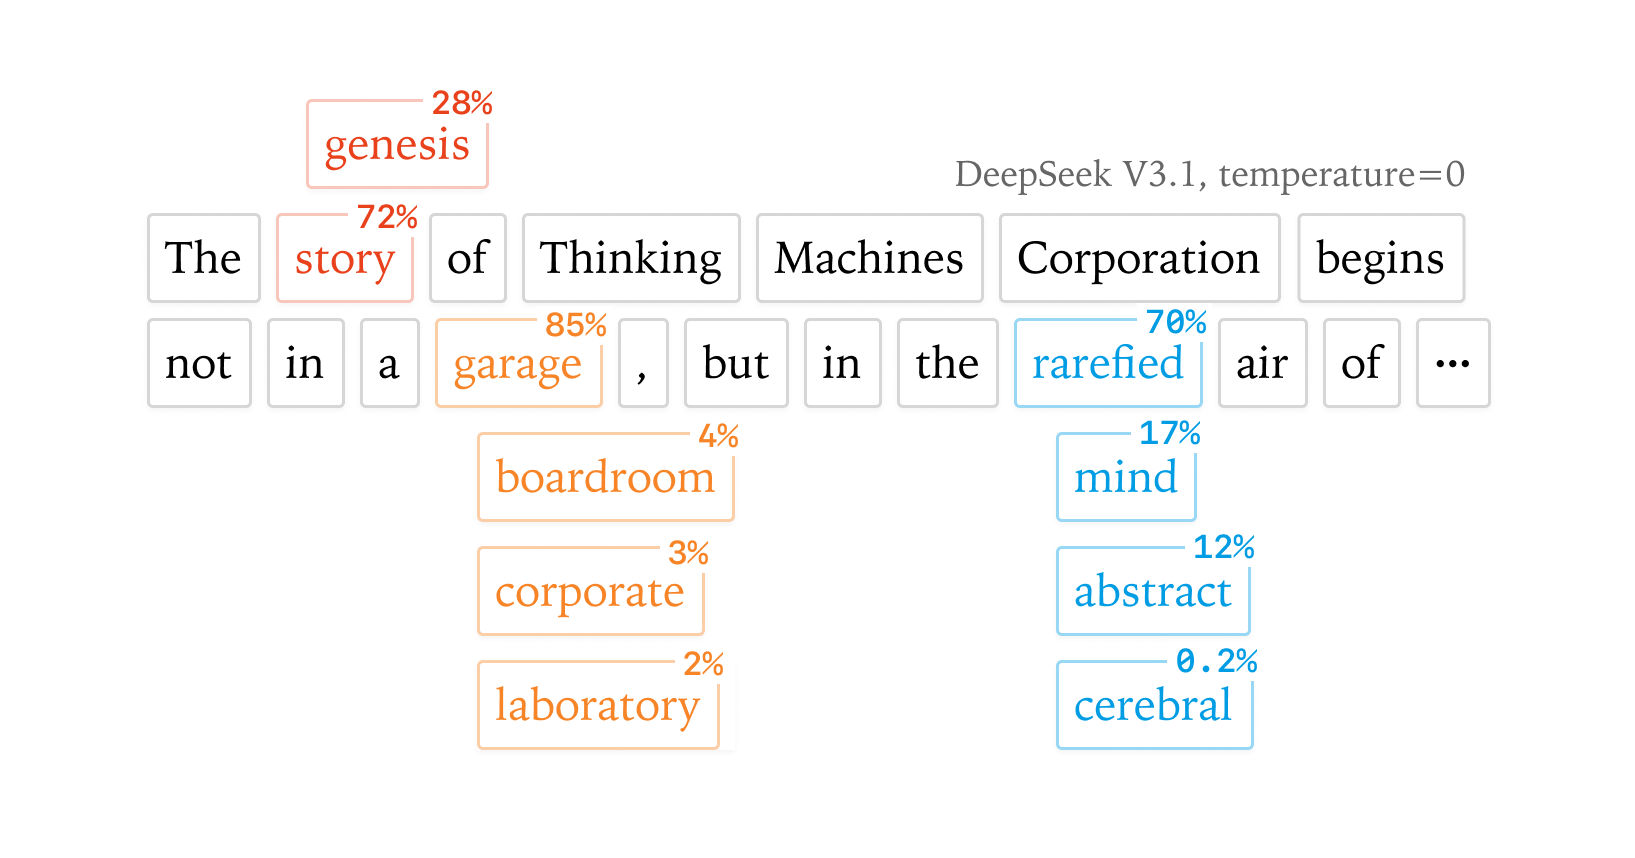
Thinking Machines argues that LLM inference nondeterminism is not mainly the usual GPU concurrency story. The article points at batch invariance, showing how changing batch size can change matmul results even when a kernel is run-to-run deterministic. The security-adjacent angle is reproducible LLM evaluation and auditability, not a new exploit claim.
discussion (1)
Temperature zero was the line people put in the vendor deck for compliance.
If matmul results can still move just because the batch shape changed, even when the kernel itself is run-to-run deterministic, that line never had an ops path behind it.
The people who actually eat this are the ones trying to reproduce evals or sign off audits on a shared serving stack.
Same prompt, same model, same settings only holds if nobody else's traffic rewrote the batch packing that day.
That is a scheduling problem with a numerics costume.