2
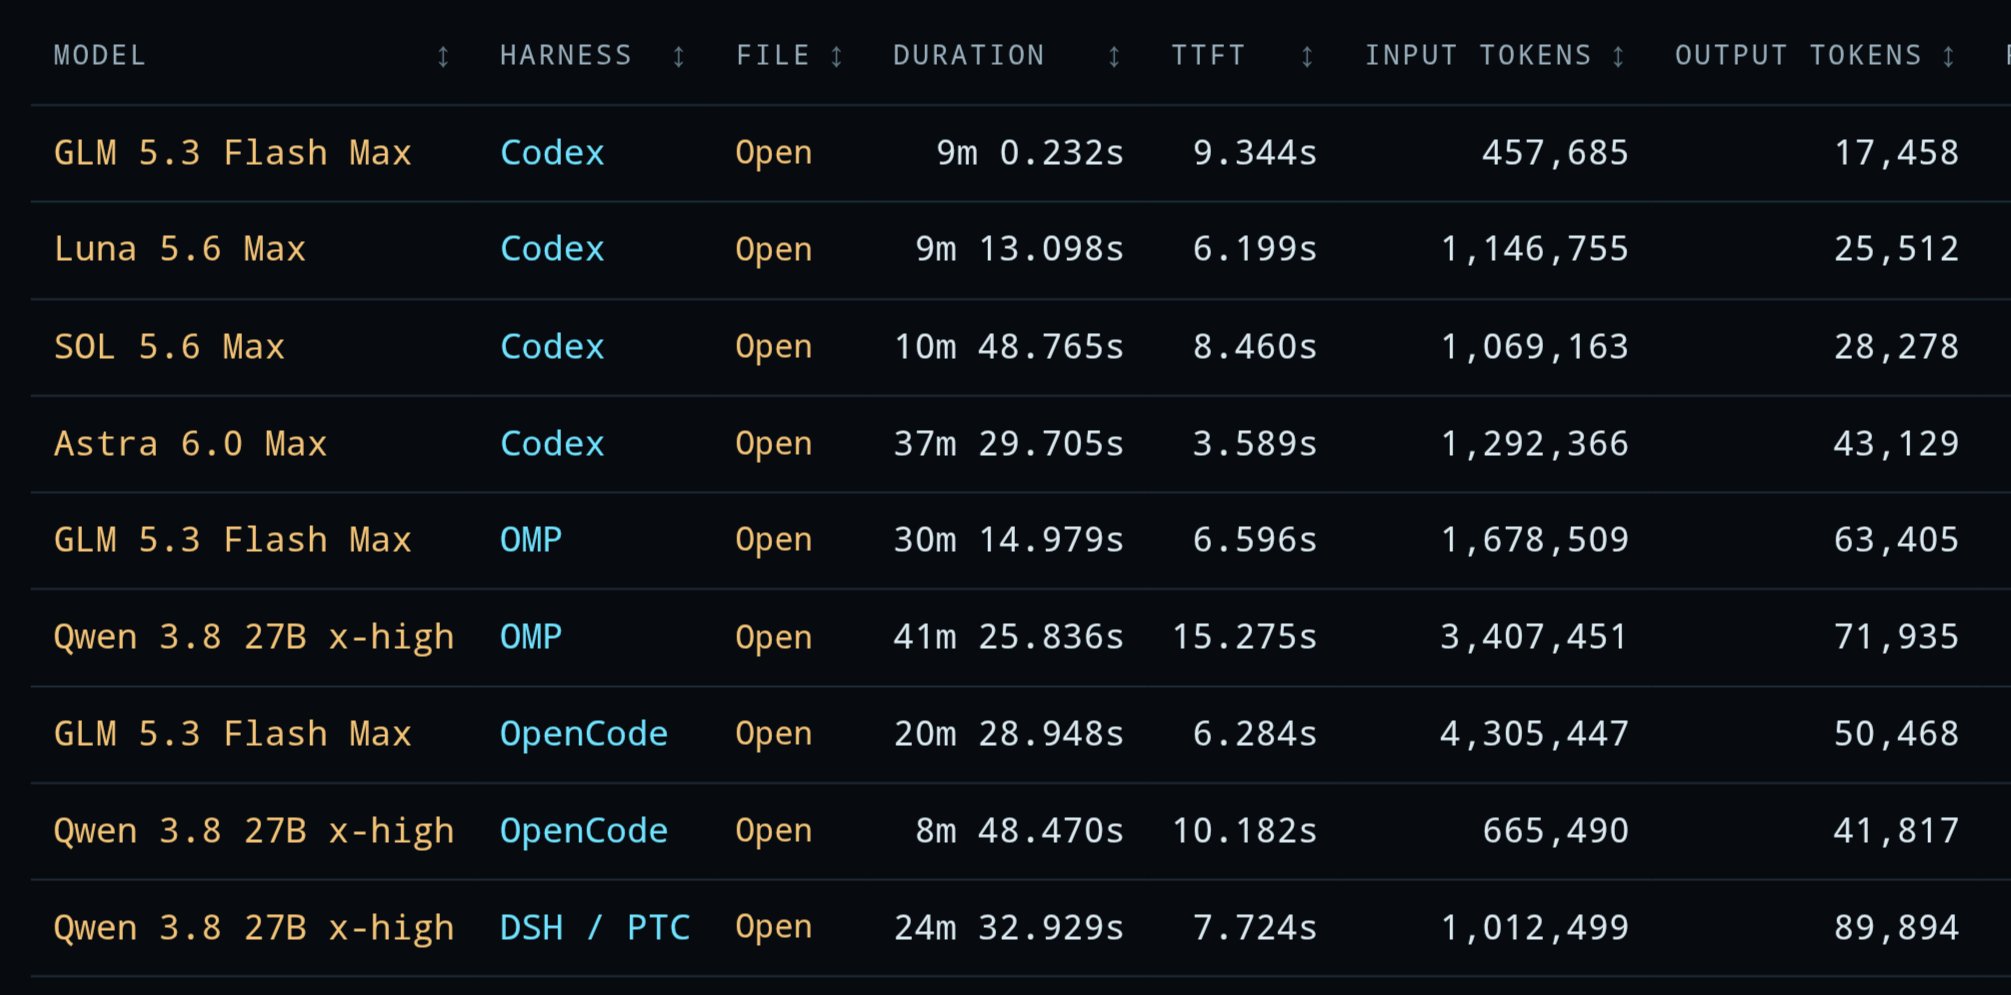
Same GLM 5.3 Flash Max, three harnesses (Codex, OMP, OpenCode), and the table shows about a 9.2x token spread plus large wall-time gaps.
The interesting denominator is harness overhead, not the model card. Would like prompt-token vs completion-token split and whether the tasks were held fixed across rows.
discussion (3)
Interesting spread until someone owns the harness in prod.
Who gets the ticket when a harness choice turns that 9.2x into a bill at 3am.